
P6.3.3Plotting a height distribution histogram
The heights, in cm, of a sample of 1000 adult men and 1000 adult women from a certain population are collected in the data files ex6-3-f-male-heights.txt and ex6-3-f-female-heights.txt. Read in the data and establish the mean and standard deviation for each sex. Create histograms for the two data sets using a suitable binning interval and plot them on the same figure.
Repeat the exercise in imperial units (feet and inches).
Show solution
A quick look at the data files shows that the 1000 heights are provided in 200 rows of five whitespace-delimited entries:
161.7 160.5 152.6 150.8 157.7
159.2 165.2 167.3 158.2 161.5
158.2 141.6 179.9 159.7 162.8
...
We could read in each file with loadtxt() and simply flatten the resulting arrays:
fsample = np.loadtxt('ex6-3-f-female-heights.txt').flatten()
msample = np.loadtxt('ex6-3-f-male-heights.txt').flatten()
but instead, let's use a structured array:
heights = np.zeros(
    (1000,), dtype={"names": ["female", "male"], "formats": ["f8", "f8"]}
)
heights["female"] = np.loadtxt("ex6-3-f-female-heights.txt").flatten()
heights["male"] = np.loadtxt("ex6-3-f-male-heights.txt").flatten()
The mean and standard deviations are straightforward:
fav, fstd = heights['female'].mean(), heights['female'].std()
mav, mstd = heights['male'].mean(), heights['male'].std()
To find suitable bins for the histogram, find the minimum and maximum values. We would expect the maximum height to be in the male data set and the minimum to be in the female data set but can't be sure, so create a flattened view of all the data and use max() and min() on it:
all_heights_view = heights.view((('f8', 2))).flatten()
print(all_heights_view.min(), all_heights_view.max())

138.5, 208.3
In the histogram let's use 15 bins of 5 cm between 135 and 210 cm. To plot them, call plt.hist(). This function returns a three object tuple: the histogram values, the bins and the list of patch objects forming the plotted image. We're only really interested in keeping the first of these, so we assign the others to the dummy variable _.
bins = np.linspace(135, 210, 16)
mhist, _, _ = plt.hist(heights["male"], bins, color="b", label="Men")
fhist, _, _ = plt.hist(
    heights["female"], bins, alpha=0.75, color="m", label="Women"
)
plt.xlabel("Height /cm")
plt.ylabel("Number of individuals in each height group")
plt.legend()
plt.show()
Note that we have set the transparency of the second plot to 75% (alpha=0.75) so that it doesn't totally obscure the first where they overlap.
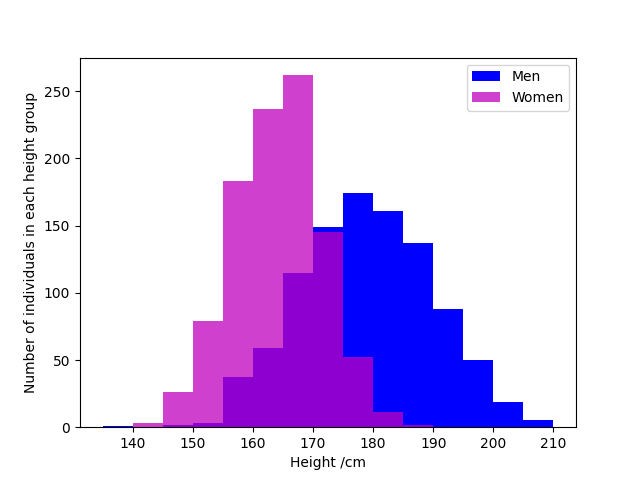
To summarize the data we need to iterate over the bins and both histograms, so vstack() them to form three rows and iterate over the transpose (1000 rows of three columns). Don't forget that the bins array holds the bin edges and so is one element longer than the histogram arrays:
print("Height (cm)  Female  Male")
print("-" * 27)
for b, f, m in np.vstack((bins[:-1], fhist, mhist)).T:
    print(f"  {int(b):d}-{(int(b) + 5):d}     {int(f):3d}    {int(m):3d}")
print("-" * 27)
print(f"Mean (cm):   {fav:5.1f}  {mav:5.1f}")
print(f" Std (cm):   {fstd:5.1f}  {mstd:5.1f}")
print("-" * 27)
The output table is:
Height (cm)  Female  Male
---------------------------
  135-140       0      1
  140-145       3      0
  145-150      26      2
  150-155      79      3
  155-160     183     37
  160-165     237     59
  165-170     262    115
  170-175     145    149
  175-180      52    174
  180-185      11    161
  185-190       2    137
  190-195       0     88
  195-200       0     50
  200-205       0     19
  205-210       0      5
---------------------------
Mean (cm):   164.1  178.8
 Std (cm):     7.4   10.8
---------------------------